Quick one before we start: AI Build Night is on tonight, 6pm London. Come along.
The scariest report I read this autumn said everything was fine.
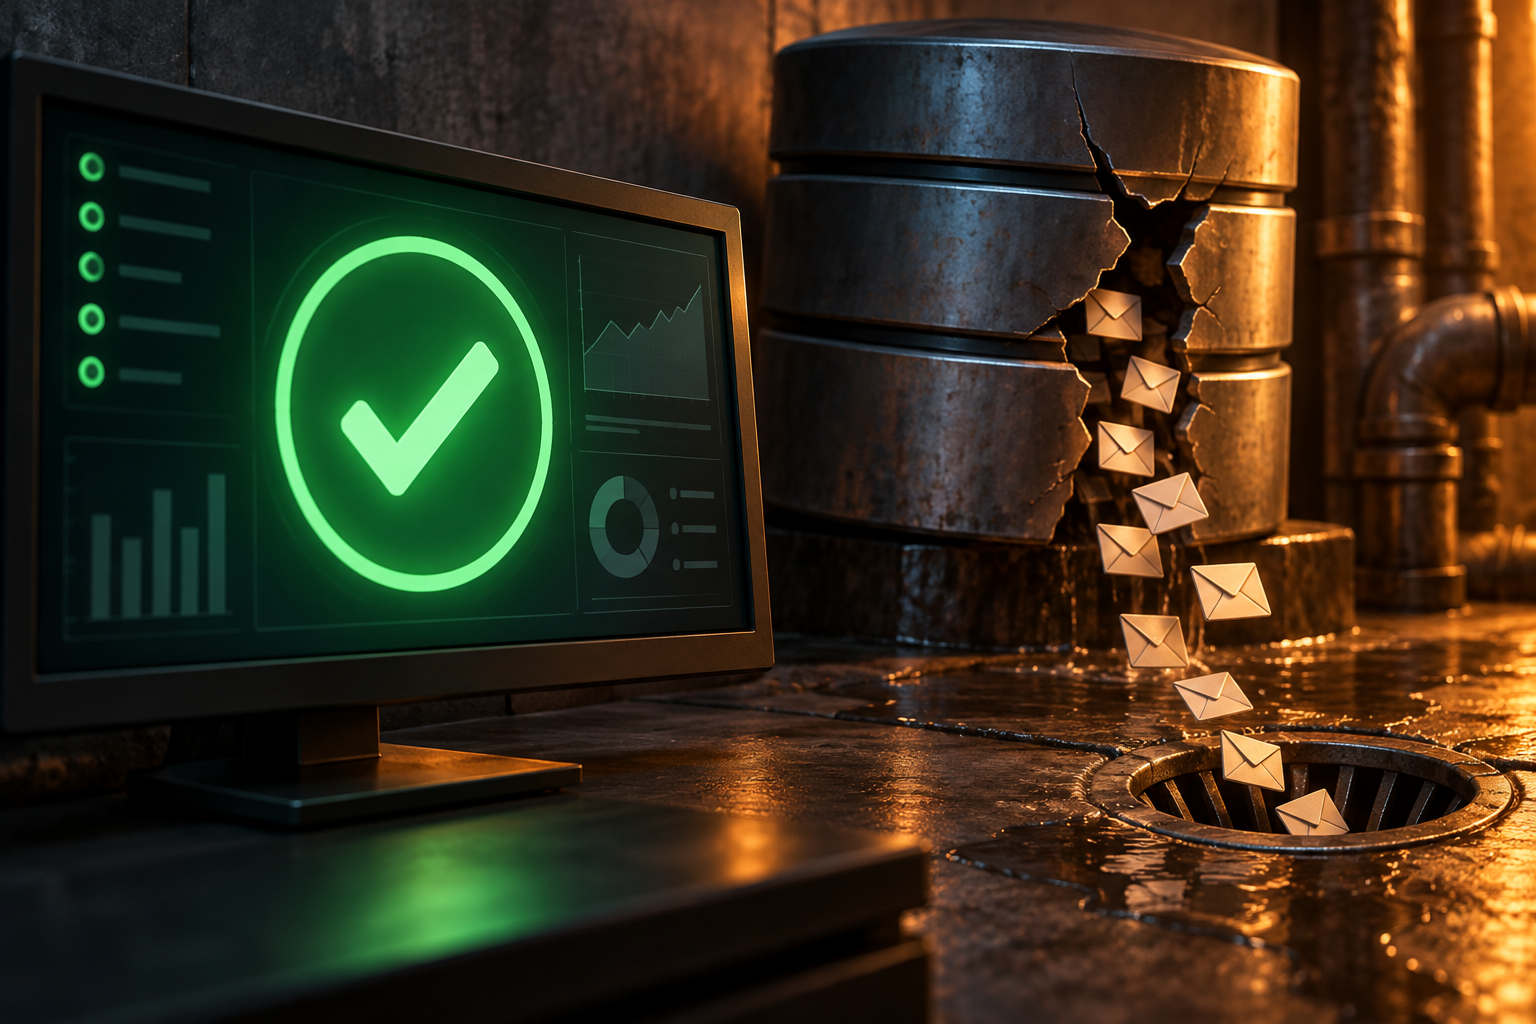
It was the summary from a new job I'd built to email people after my Monday community call. One line of output, tidy as you like: four skipped, zero errors, ok true. A green tick.
Four skipped. Why four? Nobody had unsubscribed. Nobody was suppressed. Nobody had been emailed already. I'd built the thing to skip people for exactly those three reasons, and none of them applied.
So the job had skipped four people for no reason at all. And it had told me that was fine.
What the job does
Every Monday evening I run a live call for the people in my community. They bring their business, we pull it apart on Zoom, and everyone leaves with something to fix. The recording is members only.
On Tuesday morning a script handles the tidy-up. It finds the recording, uploads it as an unlisted video, writes the recap row into the members area, and sends each person an email. Two versions: "here's the replay, thanks for coming" for the people who joined, and "sorry you missed it, here's the replay" for everyone else.
Nobody touches it. And that's the point. I build these things so a Tuesday morning doesn't need me.
The first real run was the Tuesday after the first call, 29 September. Until then I'd only tested it with dry runs, which preview what would be sent and send nothing.
The green tick that meant nothing
But the output looked plausible, which is the dangerous bit. If it had said "errors: 4" I'd have been on it in a minute. Errors get noticed. They have a red colour and a nasty exit code.
"Skipped" is a polite word. In this job it meant "I decided not to send this one, and I have a good reason". A healthy run with nobody to email would also say skipped. So the number could have meant nothing was wrong, or everything was.
So I checked the log table the emails are recorded in. Empty. Not a single row for this kind of email, ever, since the feature shipped. Zero emails had ever gone out.
Where it broke
Before each send, the function writes a claim row into a log table. That's how it avoids emailing the same person twice if the job runs again. No claim row, no email.
The log table had a rule on it: the "mode" column could only hold two values, the ones used by the Monday reminder emails. When I built the post-event emails, I added a third mode and a new column, and I wrote the code and the comments. I never widened the rule.
So every claim insert hit the database, got rejected for breaking that rule, and landed in a catch block. And the catch block did the helpful thing I'd written it to do. It counted the failure as a skip and carried on.
That's the whole bug. One database rule, one catch block, and a counter filed under the wrong heading. The dry runs never touched the table, so they never saw it. The code was fine. The job was fine. The database just refused every write, and my own summary relabelled the refusals as good manners.
The fix, and the rule I took from it
But the repair took minutes. I widened the rule on the live database, saved the same change as a migration file so a fresh setup matches production, and patched the original migration too. Then I re-ran the job. Four emails went out, each with a real delivery ID back from the email service. Sent four, skipped zero, errors zero.
And the rule I took is the useful bit for your business, whatever you run it on:
A skip is not a pass. If a number can mean "nothing to do" or "couldn't do it", it will eventually hide a failure. So now I check that the skips add up. Skipped four means I should be able to name the four reasons: unsubscribed, suppressed, already emailed, opted out. If the reasons don't add up to the total, I treat the gap as a failure. The job still prints the same line, but I don't trust it until the arithmetic works.
You can do the same with a spreadsheet and a cup of tea. Anything that reports "fine" to you, an invoice chaser, a booking reminder, a review request, ask what the number would look like if it were silently broken. If the answer is "exactly the same", you don't have a report. You have a green light that's wired to nothing.
This week, the same job got tested again
On Tuesday 3 November the same script ran into a different wall. YouTube has a daily cap on uploads, and it said no. The upload failed with a quota error.
But this time the structure held. The video step failed loudly, flagged as an error, and the email step carried on regardless. The four emails went out saying the replay was on its way, and the retry slots later in the day were set to try the upload again once the quota reset. Nobody had to wake me up. The two jobs don't wait on each other, which is a decision I'd make again as well.
The bit I haven't fixed
Look, I'll be straight with you, because this is the part of proof of work people leave out.
Every run I have a record of has sent the "you missed it" version to everyone. Zero attendees detected, every time. The job decides who attended using Zoom's join events and Zoom's participant list. The participant lookup keeps returning "meeting does not exist" once the call has ended, and the fallback path finds nobody.
So either nobody came to my Monday call for five weeks, which I doubt, or the attendance check is broken, which I think is more likely. I haven't proven which. So as it stands, the people who showed up may have been emailed a polite note saying sorry they missed it.
That's a real flaw in a live system, and it's on my list. And it's also the same disease as the first bug. The job reports a clean-looking result, and the result might be wrong without anyone knowing. I only found it because I now ask what a broken version would look like, and a "zero attendees, five weeks running" line is exactly what a broken version looks like.
What you can take from this
But you don't need to be building Zoom integrations to use any of it.
- Test the write, not just the logic. A dry run proves the code works. It doesn't prove the database will accept what the code produces. Do one real send to a test address before you trust a new automation.
- Make failures louder than successes. A catch block that says "skipped" is lying. If something couldn't happen, it's an error, in red, in your inbox.
- Make the numbers add up. Total handled should equal sent plus every named reason for not sending. If it doesn't, you have a gap, and gaps are where bugs live.
- Keep steps independent. The video upload failing shouldn't stop the emails. The emails failing shouldn't stop the recap.
- Write down what you haven't fixed. An open problem you've named is a lot safer than a closed one you only think you've solved.
Next time something of yours reports "all good", ask it one question. What would you look like if you were broken?
Tonight's AI Build Night. 6pm London, live on Zoom, me building one of these systems from scratch while you watch. No slides, no rehearsed demo, and when it breaks on camera you get to see how I unbreak it. That's usually the useful bit. Grab a seat.
Brewed by Steven, poured by Viktor
About Steven Tann: Steven helps business owners build systems that run themselves using AI. After 10+ years helping 7,000+ businesses and building his own autonomous operations, he's the bloke who actually does it, not just talks about it. Find out more at steventann.com.