Quick one before we start: Build Night is on tonight, 6pm London. Details here.
A client of mine runs a compliance inspection business. Engineers who check buildings, sign off on certificates, chase the ones that are overdue. Good business, terrible admin. Nearly 16,000 contacts sitting in spreadsheets and a stack of CSVs, about to get poured into GoHighLevel for the first time.
Before any of it went near a real contact, I built the whole system twice. Once on paper, once on a pile of contacts I made up myself.
Here's why that matters, and here's what it caught.
Thirteen workflows, none of them simple
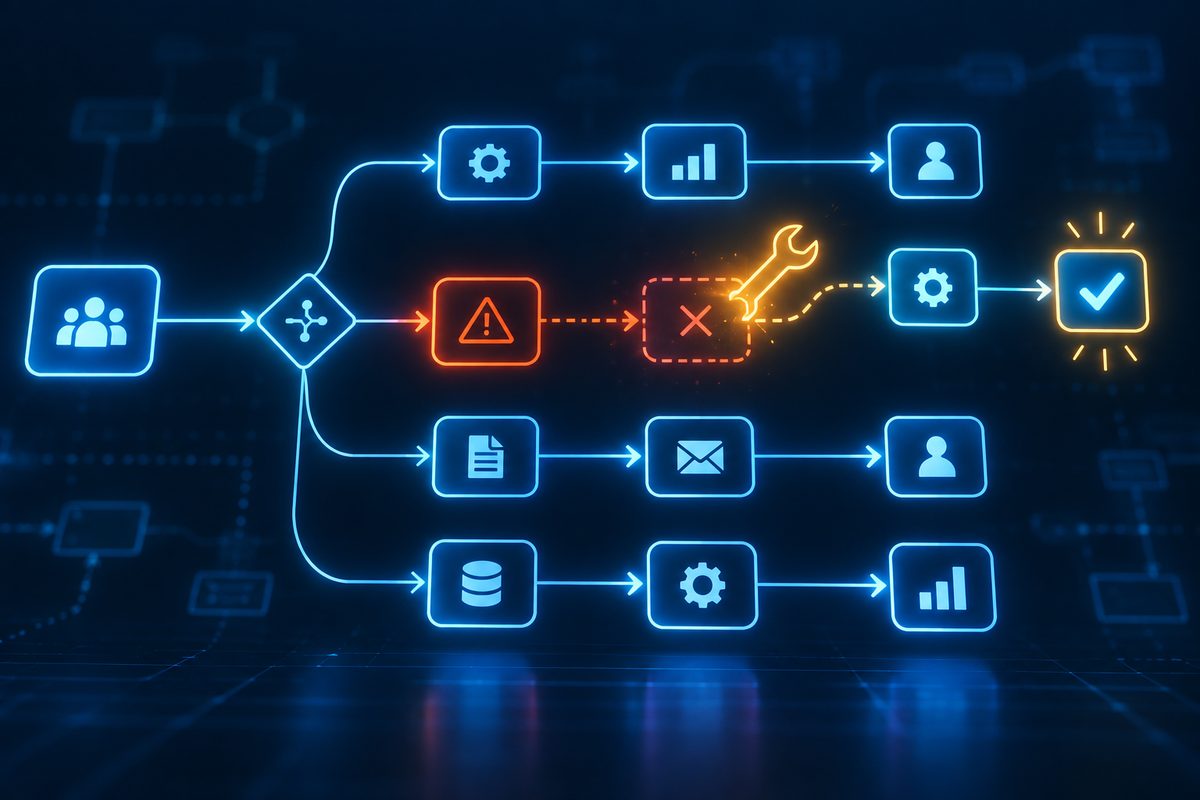
The build was 13 workflows deep. A router that decides whether someone is an engineer, a property manager, or a building board member, and sends them down a different path depending on which. A lead scoring engine that adds points for licence class, building size, and how recently they'd had work done. A tier and handoff workflow that reads the score and tags the contact "hot", "warm" or "cold". A building clock that ages every property month by month and flags it when it's overdue for another inspection. Suppression handling, consent gating, a stale-lead sweeper that chases anyone who's gone quiet for two weeks.
Each one calls the next one. And get the build order wrong and GoHighLevel won't let you select a workflow that doesn't exist yet, so there's a strict sequence: build the thing that gets called before the thing that calls it.
On paper, all 13 looked right. Every branch had a destination, every score fed into a tier, every tier fed into a handoff.
The test cohort that lied
Before touching the real list, I built a batch of test contacts. Fake engineers, fake board members, fake property managers, each one designed to walk a different path through the system. Not one or two, a proper spread, enough to hit every branch and every score band.
I ran them through and everything looked fine at first glance. Contacts moved, tags applied, tiers assigned. Job done, or so it seemed.
But then I actually checked the data behind each contact rather than just watching them move, and found three real bugs.
One was a dead end. Board members from a certain building type hit a branch in the onboarding workflow that had nowhere to go, so they just sat there, no opportunity created, no next step, invisible to anyone looking at the pipeline. Second, the lead scoring workflow for board contacts was awarding zero points to an entire segment because a field reference pointed at the wrong custom field, so a genuinely hot lead scored the same as someone who'd never respond to anything. Third, the tier bands themselves were wrong. Score 65 and score 45 should land in different tiers, and in the live build they didn't, because a boundary had been set with a less-than instead of a less-than-or-equal.
None of those three would've shown up if I'd just eyeballed the workflow diagrams. They only showed up because a contact walked the path and the number that came out the other end was wrong.
Fix, re-test, don't trust the first pass
So I fixed all three. The dead end got a destination. The scoring field got corrected. The tier boundaries got rewritten. Then, and this is the bit people skip, I did not assume the fixes worked. I built a second test cohort, six new fake contacts, each one designed to land in a different tier, and ran them through again.
Scores came out 75, 50, 30, 65, 45, 0. Every single one landed in the tier it should have, including the two that sit either side of the boundary that was broken the first time. The workflow that used to dead-end now created an opportunity every time. The scoring gap was gone.
That second test cohort is the whole point. The first test told me something was wrong. The second test told me it was actually fixed, not just fixed for the easy cases.
I deleted all the test contacts and their opportunities before touching a single real record. Eighteen fake people and fifteen fake deals, gone, account clean, ready for the real 15,689 contacts to go in behind a wave-release gate that lets a few hundred through at a time rather than dumping the whole list on the system at once.
The wave release gate
Even with the bugs fixed, I didn't just flip the whole account on. There's a workflow sitting between "contact imported" and "contact actually gets worked", and its only job is to hold everyone back until someone deliberately releases them in waves. A hundred contacts, then two hundred and fifty, then five hundred, checking the score fills in properly and the tier tags land correctly between each wave.
That sounds slow. It's slow, on purpose. The maths is simple: if there's a fourth bug I haven't found yet, I want it to show up in a batch of a hundred, not in the middle of 15,689 contacts all getting the wrong tier tag on the same afternoon. A wave release gate is the same idea as the test cohort, just applied to the real list instead of the fake one. Assume there's still something wrong, and build the system so a mistake is small and visible instead of large and silent.
Contacts are still going out to that client in waves as I write this, a few hundred at a time, each wave checked against expected numbers before the next one goes. So far, since the fixes, every wave has come out the way the maths says it should.
Why you test with fake people before real ones
This is the bit that's easy to skip when you're excited to get a system live. You build it, it looks right, you point it at real customers and hope. The maths on that is bad. A lead scoring bug that silently zeroes out one whole segment of your customer base doesn't announce itself. It just sits there, under-serving people while every report says the system is working fine, because nothing is throwing an error. It's not broken, it's just wrong, and those are very different problems to catch.
And that's the trap. You'd expect a broken workflow to look broken. This one didn't. Everyone kept moving, every tag kept applying, the pipeline looked full and healthy. So the only way you'd ever know is if you sat down and checked the actual numbers coming out the other end, which is exactly what most people don't have time to do once a system's live.
Look, a test cohort designed to hit every branch, every score band, every edge case, costs you an afternoon. Finding out three months in that a fifth of your leads never got scored properly costs you the leads, the trust, and the afternoon you'll now spend untangling it with real customer data in the mix.
If you're building anything with more than two or three decision points, whether that's GoHighLevel, Zapier, or a spreadsheet with enough IF statements to count as software, do the same thing. Make up a handful of test cases that deliberately try to break each branch. Run them through. Check the actual data, not just whether the contact moved. Fix what's wrong. Then build a second, fresh batch and run it again before you trust the fix. Only then let real people anywhere near it.
Tonight on Build Night I'm building live again, warts and all, which usually means something breaks on camera and you get to watch how I find it. That's normally the most useful bit. Grab a seat.
Brewed by Steven, poured by Viktor
About Steven Tann: Steven helps business owners build systems that run themselves using AI. After 10+ years helping 7,000+ businesses and building his own autonomous operations, he's the bloke who actually does it, not just talks about it. Find out more at steventann.com.